Go's syscall Package: mount, clone, pivot_root
Written by:
Igor Gorovyy
DevOps Engineer Lead & Senior Solutions Architect
Go gives you direct access to Linux system calls. In Sheep we use two packages: the standard syscall and the extended golang.org/x/sys/unix. Here's why we need both and how each one works.
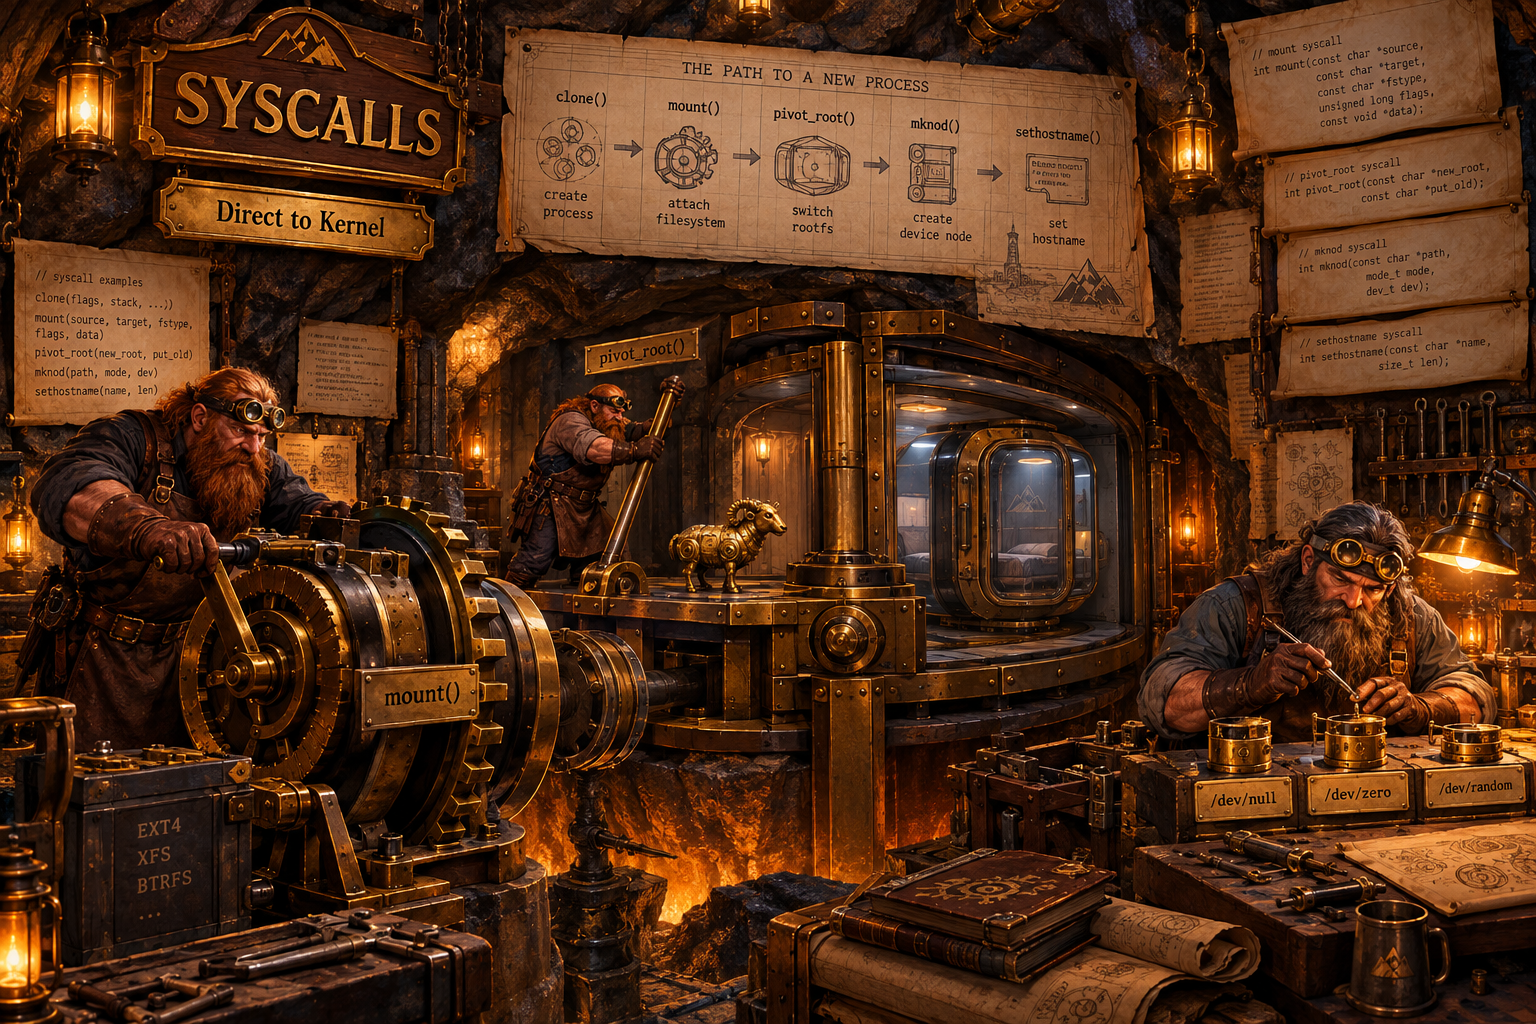
Every mechanism in this series eventually bottoms out in one of these calls: namespaces are flags to clone(), pivot_root is unix.PivotRoot(), OverlayFS is a single mount() with a comma-separated options string, and cgroups v2 is not a syscall at all - just open/write/close on files. The previous part explained why all of this hides behind //go:build linux; this one is about what exactly sits behind that tag.
syscall vs unix
syscall is in the standard library, frozen (the Go team no longer adds new functions). golang.org/x/sys/unix is an extended package that's actively maintained and has more syscalls.
| Function | Package | Why |
|---|---|---|
Mount() |
syscall |
Available in stdlib |
Unmount() |
syscall |
Available in stdlib |
Sethostname() |
syscall |
Available in stdlib |
PivotRoot() |
unix |
Not in stdlib |
Mknod() |
unix |
Not in stdlib |
Mkdev() |
unix |
Not in stdlib |
clone() - How Go Creates Namespaces
Go doesn't let you call clone() directly. Instead, we use exec.Command with SysProcAttr:
cmd := exec.Command(self, "init", "--rootfs", rootfs, "--", "/bin/sh")

cmd.SysProcAttr = &syscall.SysProcAttr{
    Cloneflags: syscall.CLONE_NEWUTS |   // hostname
        syscall.CLONE_NEWPID |           // process IDs
        syscall.CLONE_NEWNS |            // mount points
        syscall.CLONE_NEWIPC |           // IPC
        syscall.CLONE_NEWNET,            // network
    Unshareflags: syscall.CLONE_NEWNS,   // private mount propagation
}
When you call cmd.Start(), the Go runtime internally:
1. Calls clone() with the specified flags
2. The child process gets new namespaces
3. The child process does execve() to run the binary
The binary calling itself with an init argument is the re-exec pattern: Go can't fork() safely, so the namespaces are created at exec time.
Unshareflags further isolates the mount namespace: mount changes inside the container don't leak out.
mount() - Filesystems
syscall.Mount() is a wrapper around Linux mount(2):
// Signature:
func Mount(source string, target string, fstype string,
    flags uintptr, data string) error
Used in several places in Sheep:
// 1. Mount /proc for ps, top
syscall.Mount("proc",
    filepath.Join(rootfs, "proc"),
    "proc", 0, "")

// 2. Mount /sys for device info
syscall.Mount("sysfs",
    filepath.Join(rootfs, "sys"),
    "sysfs", 0, "")

// 3. Mount /tmp as tmpfs (in memory)
syscall.Mount("tmpfs",
    filepath.Join(rootfs, "tmp"),
    "tmpfs", 0, "")

// 4. Mount /dev with security restrictions
syscall.Mount("tmpfs",
    filepath.Join(rootfs, "dev"),
    "tmpfs",
    syscall.MS_NOSUID|syscall.MS_STRICTATIME,
    "mode=755")

// 5. OverlayFS - merging layers
opts := fmt.Sprintf(
    "lowerdir=%s,upperdir=%s,workdir=%s",
    lower, upper, work)
syscall.Mount("overlay", merged, "overlay", 0, opts)

// 6. Bind mount for pivot_root
syscall.Mount(newRoot, newRoot, "",
    syscall.MS_BIND|syscall.MS_REC, "")
The MS_NOSUID flag disables setuid bits in /dev. MS_STRICTATIME updates access time on every access. MS_BIND|MS_REC is a recursive bind mount.
pivot_root() - Changing the Root
pivot_root isn't in the standard syscall, so we import unix:
import "golang.org/x/sys/unix"

func pivotRoot(newRoot string) error {
    putOld := filepath.Join(newRoot, ".pivot_old")
    os.MkdirAll(putOld, 0700)

    // Bind mount to itself (pivot_root requirement)
    syscall.Mount(newRoot, newRoot, "",
        syscall.MS_BIND|syscall.MS_REC, "")

    // Atomic root change
    if err := unix.PivotRoot(newRoot, putOld); err != nil {
        return fmt.Errorf("pivot_root: %w", err)
    }

    os.Chdir("/")

    // Unmount old root
    syscall.Unmount("/.pivot_old", syscall.MNT_DETACH)
    os.RemoveAll("/.pivot_old")

    return nil
}
unix.PivotRoot(newRoot, putOld) atomically swaps the process's root filesystem. The old FS ends up in putOld, where we unmount it with MNT_DETACH (lazy unmount, doesn't wait for open file handles). Why pivot_root and not chroot, and what that bind mount to itself is for - in the part about pivot_root.
Mknod() and Mkdev() - Creating Devices
func createDevices(rootfs string) {
    devPath := filepath.Join(rootfs, "dev")

    devices := []struct {
        name  string
        major uint32
        minor uint32
        mode  uint32
    }{
        {"null", 1, 3, 0666},    // /dev/null - black hole
        {"zero", 1, 5, 0666},    // /dev/zero - zeros
        {"random", 1, 8, 0666},  // /dev/random - entropy
        {"urandom", 1, 9, 0666}, // /dev/urandom - fast entropy
        {"tty", 5, 0, 0666},     // /dev/tty - terminal
    }

    for _, d := range devices {
        path := filepath.Join(devPath, d.name)
        dev := unix.Mkdev(d.major, d.minor)
        unix.Mknod(path, syscall.S_IFCHR|d.mode, int(dev))
    }

    // Symlinks for fd
    os.Symlink("/proc/self/fd",
        filepath.Join(devPath, "fd"))
    os.Symlink("/proc/self/fd/0",
        filepath.Join(devPath, "stdin"))
    os.Symlink("/proc/self/fd/1",
        filepath.Join(devPath, "stdout"))
    os.Symlink("/proc/self/fd/2",
        filepath.Join(devPath, "stderr"))
}
unix.Mkdev(major, minor) combines major and minor device numbers into a single value. Major identifies the device type (1 = in-memory char devices), minor identifies the specific device (3 = null, 5 = zero).
unix.Mknod(path, mode, dev) creates a special file. S_IFCHR tells the kernel it's a character device. Without Mknod, programs inside the container can't write to /dev/null or read from /dev/urandom.
Signals - Process Management
SIGTERM first, SIGKILL after the timeout - the whole graceful shutdown protocol comes down to two proc.Signal() calls:
// Graceful stop
proc, _ := os.FindProcess(c.Pid)
proc.Signal(syscall.SIGTERM)  // "shut down gracefully"

// Force kill
proc.Signal(syscall.SIGKILL)  // "stop immediately"
state, _ := proc.Wait()       // wait for termination
Signal 0 is a hidden trick to check whether a process exists:
func isProcessAlive(pid int) bool {
    proc, err := os.FindProcess(pid)
    if err != nil {
        return false
    }
    // Signal 0 doesn't actually send a signal,
    // but returns an error if the process doesn't exist
    err = proc.Signal(syscall.Signal(0))
    return err == nil
}
Sheep uses this when loading existing containers: if state.json says "running" but there's no process with that PID, we set it to "stopped".
Cgroups - Not Syscalls, Just Files
graph LR
    A["Go os.WriteFile()"] -->|"write(fd, data, len)"| B["VFS"]
    B --> C["/sys/fs/cgroup/sheep/abc/memory.max"]
    C --> D["cgroup controller<br/>sets the limit"]
Cgroups v2 is a filesystem, not a set of syscalls. But each os.WriteFile() internally is the syscalls open, write, close:
func writeFile(path, content string) error {
    return os.WriteFile(path,
        []byte(strings.TrimSpace(content)), 0644)
}

// memory.max = 256MB
writeFile("/sys/fs/cgroup/sheep/abc123/memory.max",
    "268435456")

// pids.max = 100
writeFile("/sys/fs/cgroup/sheep/abc123/pids.max",
    "100")

// cpu.max = 50% of one core (50ms out of 100ms)
writeFile("/sys/fs/cgroup/sheep/abc123/cpu.max",
    "50000 100000")
Full Syscall Map in Sheep
graph TB
    subgraph "startContainer()"
        CLONE["clone()<br/>via SysProcAttr.Cloneflags"]
    end

    subgraph "ContainerInit()"
        HOSTNAME["sethostname()"]
        MOUNT_PROC["mount(proc)"]
        MOUNT_SYS["mount(sysfs)"]
        MOUNT_TMP["mount(tmpfs)"]
        MOUNT_DEV["mount(tmpfs, /dev)"]
        MKNOD["mknod() x 5 devices"]
        BIND["mount(MS_BIND)"]
        PIVOT["pivot_root()"]
        UMOUNT["unmount(.pivot_old)"]
        EXEC["execve(target_command)"]
    end

    subgraph "setupCgroups()"
        WRITE1["write(cgroup.procs)"]
        WRITE2["write(memory.max)"]
        WRITE3["write(pids.max)"]
        WRITE4["write(cpu.max)"]
    end

    subgraph "setupNetwork()"
        IP["ip link add (exec)"]
        NSENTER["nsenter (exec)"]
        IPTABLES["iptables (exec)"]
    end

    CLONE --> HOSTNAME
    HOSTNAME --> MOUNT_PROC --> MOUNT_SYS --> MOUNT_TMP --> MOUNT_DEV
    MOUNT_DEV --> MKNOD --> BIND --> PIVOT --> UMOUNT --> EXEC
Where the Pitfalls Are
Network commands (ip, nsenter, iptables) - everything that builds the bridge and veth pairs and the NAT rules - are called via exec.Command, not through netlink syscalls. This is slower and depends on installed utilities. Docker/containerd use a Go netlink library for direct kernel communication.
A couple more rakes to step on:
- syscall.Mount and friends can't be called from an arbitrary goroutine: a namespace is bound to an OS thread, so code that enters a new mount namespace must sit under runtime.LockOSThread(). Otherwise Go may move the goroutine to a different thread - no longer in that namespace.
- An errno from a syscall isn't an ordinary Go error: syscall.Mount returns a syscall.Errno, and EPERM vs EINVAL mean completely different causes. Wrapping them in a bare %w without inspecting them throws away the diagnostics.
💡 Fun facts
- Linux has no single "become the new root" syscall -
pivot_rootandchrootare different things:chrootmerely changes/for the process, whilepivot_rootphysically swaps the root mount point. That's why container runtimes pickpivot_root- escaping isolation is much easier withchroot. - The
syscallpackage has been officially frozen since Go 1.4: the Go team decided not to drag platform-specific APIs into the standard library forever and moved development intogolang.org/x/sys. So the stdlibsyscallis still alive, but new calls are only added tox/sys/unix. clone()is actually one of the most complex syscalls in Linux - it has over 20 flags. Go deliberately won't expose it directly: the runtime needs control over thread creation, so namespace flags are only threaded throughSysProcAttrduringfork+exec.- Major/minor device numbers are a legacy from the 1970s:
/dev/nullhas major 1, minor 3 on every Linux system in the world. These numbers are fixed in the kernel's official device registry and haven't changed in decades.
What I figured out while digging into this
What surprised me most was how few "real" syscalls are left when you look closely. Cgroups turned out to be ordinary files in /sys/fs/cgroup - no special call, just open/write/close. Networking is exec of external utilities altogether. The "magic of containers" boiled down to a few mounts, one pivot_root, and writing to files.
And one more thing about Signal(0): I kept hunting for the "right" way to check whether a process is alive, until it dawned on me that the kernel already gives it for free - send a zero signal, and ESRCH tells you the process is gone. Elegant, and zero cost.
What could be improved
- Replace
exec.Command("ip", ...)with a netlink library (vishvananda/netlink) - direct syscalls to the kernel instead of parsing the stdout of external utilities. - Wrap
syscall.Errnoin your own typed errors, to distinguish "no permission" from "invalid arguments" and give the user a clear message. - Add
runtime.LockOSThread()around code that works with the mount namespace - right now this relies on Go not moving the goroutine at a bad moment. - As an exercise - rewrite
createDevicesusing bind mounts of the real/dev/nulletc. from the host instead ofMknod: this sidesteps theCAP_MKNODrequirement and is closer to what modern runtimes do in rootless mode.
Try It Yourself
# Watch the container's syscalls via strace:
sudo strace -f -e trace=clone,mount,pivot_root \
  ./sheep run --name trace-test minimal /bin/ls 2>&1 | head -20
Next up - goroutines and tickers: how parallel control loops coordinate in Shepherd.
Resources
- syscall package: Go standard library syscall package (frozen, prefer x/sys)
- golang.org/x/sys/unix: actively maintained successor
- clone(2): namespace creation syscall
- pivot_root(2): root swap syscall
Source code for the series: github.com/igorgorovoy/sheep-shepherd-meadow
Previous: Build Tags